After the release of Claude Sonnet 5.5, one number is easy to misunderstand:
“Up to 30% savings per task.”
Does this mean:
If I previously spent $100 a month on Claude,
switching to Sonnet 5.5 would reduce it to $70?
Not necessarily.
Because Anthropic has not directly discounted Sonnet’s Token price by 30%.
Sonnet 5.5 Token prices haven’t changed
The current API prices for Claude Sonnet 5.5 are:
- Input: $2 per million tokens
- Output: $10 per million tokens
- Cache Read: $0.20 per million tokens
This is the same as Sonnet 5.
So:
If you use the same 1 million tokens, you won't be charged just 70% of before.
What Anthropic means by “up to 30% savings” refers to something else.
True savings come from using fewer resources for the same task
Suppose completing a task used to require:
Reading a lot of context,
Multiple rounds of reasoning,
Many tool calls,
And producing a long output.
If Sonnet 5.5 can:
- Understand the problem faster
- Make fewer mistakes along the way
- Make fewer tool calls
- Use fewer tokens to finish
- Avoid repeated retries
Then:
Though token prices remain unchanged, the total cost of the entire task will decrease.
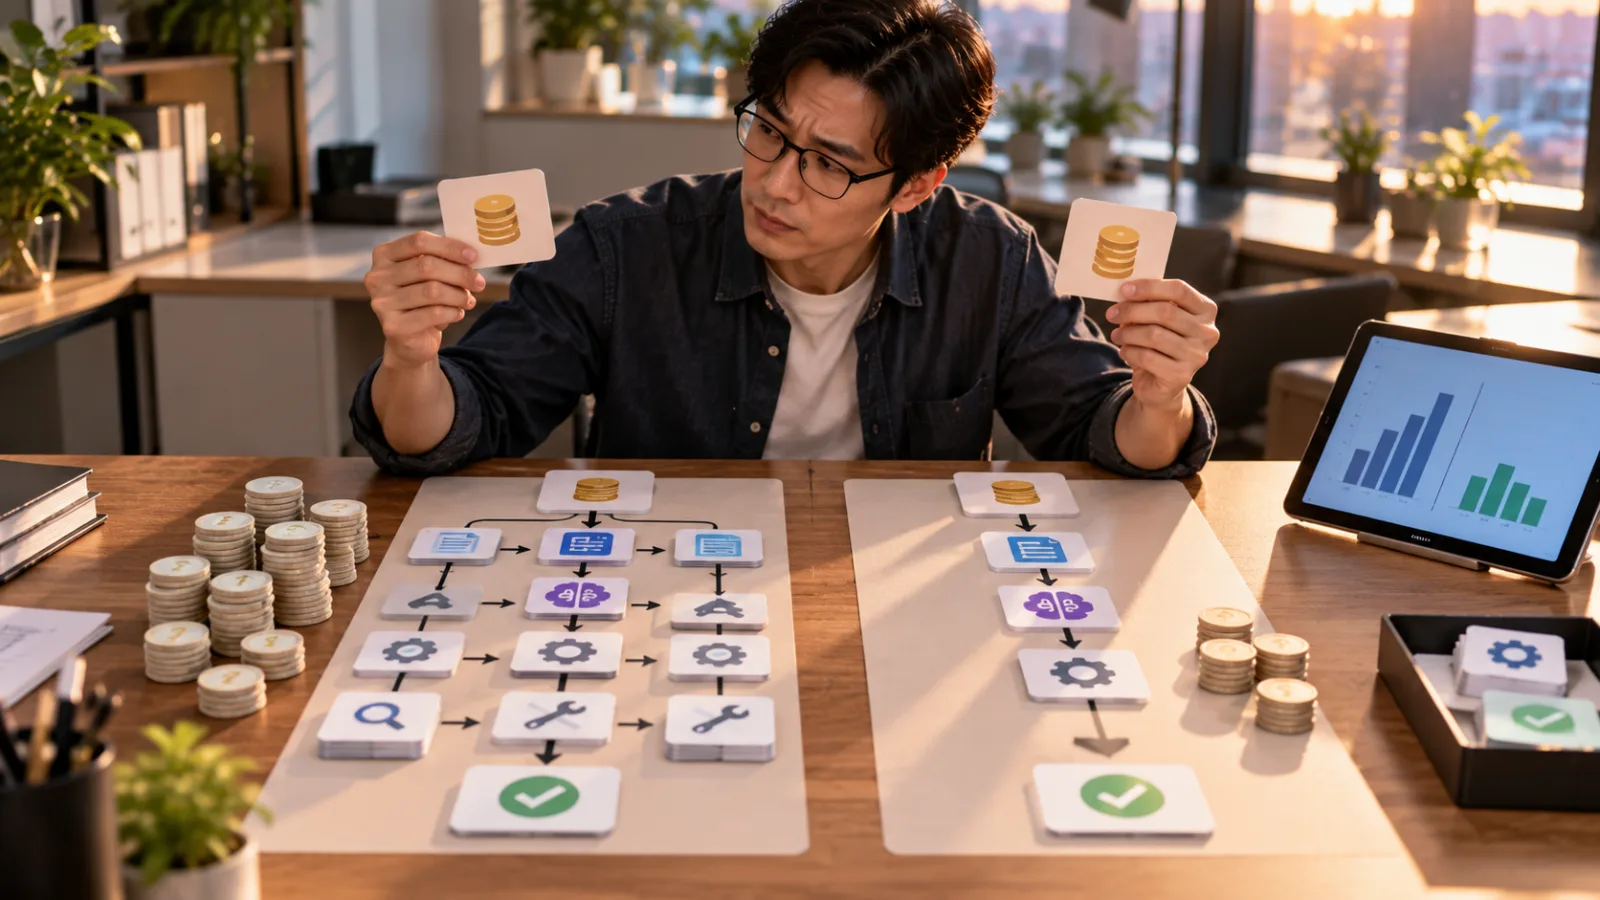
This is the concept of “Cost per Task.”
Think of it like building lunchboxes
Assume each part costs $10.
Previously, one product required 10 parts.
The cost was $100.
The new process only needs 7 parts.
Then the cost is $70.
The parts didn’t get cheaper.
Instead:
The number of parts needed to complete the same product dropped.
The “up to 30% savings” for Sonnet 5.5 is closer to this scenario.
Why does everyone's savings differ?
Because your AI tasks aren’t fixed-spec products.
Even if both call Claude for help,
The differences can be huge.
Variable 1: How complex was your task originally?
If you’re simply asking Claude:
“Summarize these three paragraphs into five points.”
The resource consumption is low to start with.
Even if the new model is more efficient, the absolute difference may not be substantial.
But if your task involves:
- Long coding sessions
- Processing large volumes of documents
- Multi-step agent tasks
- Many tool calls
- Long context analysis
Reducing even a few rounds of execution can make the difference clearer.
Variable 2: What Effort level is set?
Anthropic now lets the same model run at different Effort levels.
Lower Effort:
Faster responses, usually using fewer tokens.
Higher Effort:
The model spends more time reasoning and checking.
Anthropic currently sets defaults to:
Medium for Claude App and Claude Code,
High for Claude Platform.
So even if two users both use Sonnet 5.5,
One running many simple tasks at low Effort,
Another running complex agents daily at high Effort,
Their cost structures differ.
Variable 3: How large is the prompt?
Model efficiency doesn’t automatically mean your input data shrinks.
If every task resubmits:
- Hundreds of pages of documents,
- Large repositories,
- Full chat histories,
- Many tool definitions
Input costs remain.
Don’t assume “model saves 30%” means context size is negligible.
Variable 4: How long is the output?
Output tokens cost more than input tokens.
For Sonnet 5.5, output costs $10 per million tokens.
If your workflow is:
“The more detailed, the better, fully expanded output,”
Even if internal execution is efficient,
If output stays long, your cost savings may be erased.
Variable 5: How many rounds does the agent take?
This is critical for coding agents.
You might only give an instruction like:
“Fix this bug for me.”
But behind the scenes it might:
Search files → review code → run tests → modify → test again → find issues → modify again.
Anthropic says early testing shows Sonnet 5.5 batches tool calls more, potentially finishing in fewer steps.
This is where agents might save money.
It’s not:
One Tool Call gets 30% cheaper.
But rather:
Where previously 10 calls were needed, now fewer calls suffice.
Variable 6: Is the cache really used?
If you repeatedly have Claude read:
The same company rules,
The same large codebase,
The same tool definitions,
Prompt Cache lets some repeated context be read at lower cost.
But high cache hit rate alone doesn’t guarantee lower total cost.
Because your bill still includes:
- New input
- Output
- Cache writes
- Tool executions
- Multiple rounds of agent work
So “model efficiency” and “workflow efficiency” are separate matters.
Anthropic’s own enterprise tests don’t show everyone saving exactly 30%
This is crucial.
Anthropic’s published Early Tester results show variance.
Slack reported in their offline testing that Sonnet 5.5 used about 14% fewer output tokens than Sonnet 5.
Box observed about 12% fewer total tokens in their tests.
In a financial task, Balyasny Asset Management saw an even larger token gap.
These aren’t contradictory.
They highlight that:
Cost improvements depend heavily on the nature of the work.
So “up to 30%” shouldn’t be rewritten as:
“All users save exactly 30%.”
How can you know if you’re really saving?
The most practical way is not to guess.
Test with your own work.
For example, pick 20 real tasks you actually perform:
- 5 simple summaries
- 5 document-related tasks
- 5 coding tasks
- 5 more complex agent tasks
Then compare:
1. Was the task completed?
Cheaper but incorrect doesn’t count as savings.
2. Total token usage
Don’t just look at input tokens.
Include input, output, and cache tokens.
3. Tool/agent execution counts
Does the new model take fewer detours?
4. Manual modification time
If the model saves 20% tokens but you spend half an hour fixing results manually, it’s not cost effective.
5. Cost per successful task
Finally, calculate:
How much does it cost to truly complete a usable task?
This is the most important figure.
So what’s the answer?
Claude Sonnet 5.5 can indeed make many tasks cheaper.
But not because:
Token prices dropped 30% directly.
Rather:
The same task may require fewer tokens, fewer steps, and fewer tool calls to complete.
How much you actually save depends on your workflow:
5%?
15%?
30%?
Or maybe almost no difference in some tasks?
You need to look at your real workflow.
So when you see AI companies write:
“Up to 30% savings”
The next question shouldn’t just be:
“How much cheaper?”
But rather:
“Is it a price drop per token or a reduction in tokens needed per task?”
These two are very different.