Many companies begin building AI agents with the first cost question usually being:
“Should we switch to a cheaper model?”
But a recent Browser Agent experiment published by Asana offers a different answer:
Don't rush to change models.
Your workflow itself might repeatedly incur unnecessary costs.
This is a real case, not a hypothetical company
Asana, through its subsidiary:
StackAI
provides enterprise AI workflow automation.
One of their offerings is:
Browser Agent.
This agent can:
open websites,
read pages,
fill forms,
collect data,
and then pass results back into workflows.
The problem is:
Every step Browser Agent takes can generate more:
page text,
screenshots,
tool results,
conversation history.
If these aren’t handled efficiently, the cost for the agent to do the same work stacks up rapidly.
Asana’s real first questions were not “Which model is cheapest?”
StackAI CTO Frank Hidalgo aimed to solve two questions:
Can Browser Agent be made cheaper?
and
Can it be faster?
He had GPT-6 Astra assist within Codex to:
read the codebase,
identify how the agent creates model requests,
propose improvements,
run extensive experiments,
and then compare the results.
Hidalgo estimated that doing this manually would take
1–2 months.
They actually completed it in about
one week.
But the real value wasn’t simply saving a week of engineering time.
It was discovering a subtle issue:
Context was repeatedly being paid for again and again.
Waste #1: Fixed prompts were cached, but browsing history was not
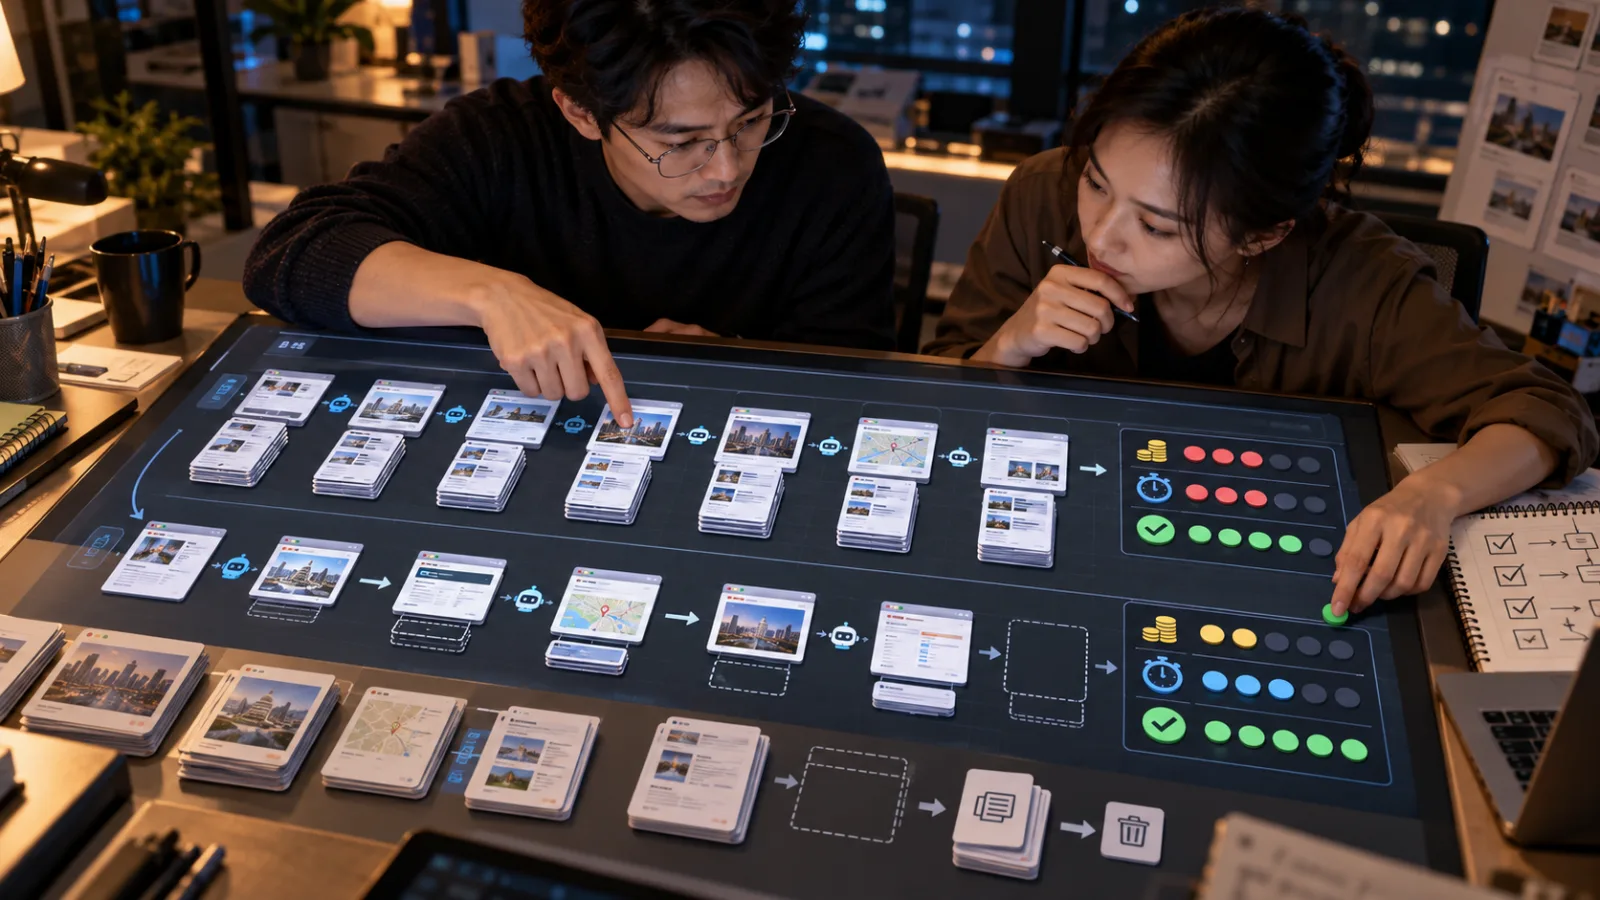
The Browser Agent needs to know what it has previously seen at every step.
So each new request includes:
system prompts,
tool definitions,
previous page text,
previous screenshots,
and operation logs.
StackAI already cached the:
fixed instructions and
tool definitions,
but the ever-growing
browsing history
was not effectively cached.
As a result, at every step, the agent resent huge amounts of previously viewed content.
Why is caching important?
Simply put, if the model service detects that:
the preceding context and last request
are exactly the same,
some models can use
cached input instead,
which is generally cheaper than reprocessing the entire content.
The catch is:
the cached content cannot have been changed.
This leads to StackAI’s second problem.
Waste #2: The agent changed old history almost every step
StackAI’s original approach:
discarded old screenshots,
truncated earlier page text,
to avoid context growing indefinitely.
This seemed reasonable intuitively.
But whenever previous history was changed,
the entire request prefix changed.
This destroyed the reuse potential of the cache.
So,
having a cache function does not mean
the cache is actually heavily utilized.
This is an important takeaway for companies from Asana’s experiment.
Waste #3: Screenshots were pruned too aggressively
Browser Agent often relies on screenshots to understand the screen.
But image context adds to cost.
So originally, old screenshots were quickly removed.
Asana later tested a different method:
don’t change history at every step.
Instead, accumulate screenshots,
and once a threshold is reached,
prune them all at once.
One of the best tests was:
keeping a maximum of
20 screenshots
and then pruning back once the limit was exceeded.
This way, across about 19 calls,
the early history remains stable,
making caching more effective.
Waste #4: This change let the agent remember more
This sounds counterintuitive.
Many try to reduce token usage by
trimming context.
But StackAI’s tests showed that with too small a history,
the agent forgets previously found information,
then has to repeat fetching,
reopening pages,
re-reading documents,
sometimes never finishing the task.
The team compared two history budgets:
120,000 characters
and
480,000 characters.
For certain newer models,
120,000 characters were insufficient.
GPT-6.1 Sol, with the smaller budget,
only completed 3 out of 18 tests.
With the larger budget,
all tests completed successfully.
So:
Less context
does not necessarily mean
lower total cost.
If AI forgets context and repeats work,
it can end up more expensive in the end.
How did they test instead of guessing?
They didn’t just change once and claim success from appearing faster results.
The formal study ran:
144 tests.
They tested:
4 different models,
2 history budgets,
6 caching/screenshot policies,
each condition repeated 3 times,
plus an additional 12 follow-ups.
Every agent worked on:
the same fixed task.
What exactly was this fixed task?
The agent had to collect from a public demo book catalog:
32 books,
6 fields each,
totaling
192 facts.
This is key because:
If model A does an easier task than model B,
comparing cost is meaningless.
Asana fixed the task,
then compared
cost,
runtime,
and result quality,
to determine which changes were actually effective.
What were the final results?
With the optimal GPT-6.1 Sol workflow,
the average estimated model cost per run was about
$0.47.
Time was approximately
4 minutes.
Compared to the original production setup using Model B,
OpenAI/Asana reported:
Costs:
76 times lower.
Speed:
5 times faster.
And under ideal conditions, the agent found all
192 facts.
But the “76 times” needs deeper breakdown
This is the most important boundary.
Don’t interpret “76x” as
“Enable cache and every AI agent becomes 76 times cheaper.”
It’s not.
The 76x comparison is between:
Original production workflow + Model B
versus
Optimized workflow + GPT-6.1 Sol.
This incorporates both:
workflow optimization
and
model differences.
Looking only at Model B,
workflow optimization reduced estimated model cost per run from at least
$36.21
to
$1.24
about
29 times lower.
This itself is huge.
It also confirms the headline 76x isn’t solely due to cache or GPT-6.1 Sol.
And the $36.21 baseline has a limitation
Some original runs hit
step limits
before completing the task.
So the
$36.21
cost is
a minimum.
This means the study compared:
two workflows under a specific
browser benchmark
, not two identical, perfectly finishing production product bills.
Therefore, you cannot directly apply
$0.47
to your company’s customer service agent,
procurement agent,
or research agent.
What should small companies really learn from this case?
Not:
“Switch to GPT-6.1 Sol immediately.”
Nor:
“Copy the 480,000 character history budget.”
The true lesson is:
When AI workflows become too expensive,
don’t start by asking:
“Which model has the lowest price?”
Break it down into four questions first.
1. Is the same context being resent repeatedly?
For example:
company policies,
product manuals,
previously read pages,
tool definitions,
conversation history.
If the whole input is resent each round,
you need to check whether
caching is truly effective.
2. Is the agent redoing work because it forgets?
Too small a context might save token costs,
but if the agent
re-opens websites,
re-searches data,
re-reads documents,
overall cost could be higher.
So don’t just look at how long each request is,
look at
total cost to complete the entire task.
3. Are images and screenshots changed every step?
This is common for computer/Browser Agent use cases.
The screen keeps changing,
screenshots keep being added,
and then deleted.
If history changes every step,
cache can’t remain stable.
What you should test is:
Which screenshots really need to be kept?
How often should you prune?
Can you batch prune?
Instead of:
seeing expensive images and simply deleting all.
4. Is the same task still being completed?
This is the most important point.
Suppose the original agent
completes 95 out of 100 runs.
If after changes, cost drops by half,
but only 60 out of 100 runs complete,
don’t say cost dropped 50% directly.
Because for those 40 failures,
you still have to re-run,
manually intervene,
or redo workflows.
You must look at:
cost per successfully completed task.
Not just single request token cost.
How can small teams adopt this method?
You don’t have to run 144 experiments.
Start with:
20 fixed cases.
Pick a task you really do daily, such as:
checking 10 competitor websites,
organizing 20 invoices,
updating 15 CRM entries,
handling 20 customer inquiries.
Fix:
inputs,
completion criteria,
answer format,
and then change only
one variable at a time.
First round, track these four numbers
Success rate
How many completions out of 20 runs?
Average cost
Average cost per completed task?
Average time
How long per task?
Manual revision time
How long does manual cleanup take after AI finishes?
These metrics are closer to a company’s true ROI than
“Model X benchmark beats Model Y.”
Then identify bottlenecks
If cost is high,
ask: Is context resent repeatedly?
If runtime is long,
ask: Is the agent repeating work due to forgetting?
If success rate is low,
ask: Is history too small, tools unstable, or is the task undefined?
If manual revision is high,
ask: Is the AI failing a critical step?
Different problems require different solutions—not always
switching models.
One more important thing Asana did: fully save every experiment
All GPT-6 Astra
requests,
data traces,
and results
were recorded in
Asana Command.
This enabled follow-up:
comparisons,
anomaly detection,
ticket creation,
pull requests,
review,
and production rollout.
This is equally important for small companies—don’t only record
“It seems faster now.”
At a minimum, track:
version,
prompt,
model,
settings,
cost,
time,
and results.
Otherwise, after two weeks,
you won’t know which change actually worked.
AI optimizing AI doesn’t mean humans can step away
Asana clearly divided tasks.
Humans do:
define goals,
choose which plans to test,
define correct answers,
review conclusions,
and review production changes.
AI does:
read code,
find bottlenecks,
set up tests,
run experiments,
analyze traces,
and organize results.
This is a typical
human + agent
work model,
not
“GPT-6 Astra deciding on production changes by itself.”
The key takeaway for enterprises:
When AI agents start running at scale,
the biggest problem might no longer be:
whether they can do the task.
But rather:
how much it costs per successful completion.
So before moving AI workflows from demos to production, you must measure at least:
success rate,
cost,
time,
and manual fixes,
not just ask,
“Did the agent succeed?”
Because an agent that always finishes a task at $30 per run
and an agent that produces the same result for $0.50 per run
are entirely different products commercially.
What Asana’s case really demonstrates isn’t the 76x, but how to turn
“AI is too expensive”
from a complaint into
an engineering problem that can be
measured,
compared,
and diagnosed.
If you want to identify which step in your workflow is best suited for AI, comment “workflow.”