This is a hypothetical business case by SasaDaily.
It is not an official OpenAI customer case.
Today’s scenario involves a:
6-person online subscription education team.
The company offers:
Online courses.
Member-only content.
Weekly live streams.
Community Q&A.
Monthly subscription.
The team is small.
But every Monday morning, they have to perform almost the same operational analysis.
CEO’s most common questions boil down to a few:
Why did this week's renewal rate drop?
Which member group unsubscribed the most?
Are new members from recent ads actually staying?
Is the increase in support requests related to cancellations?
Which courses are purchased a lot but watched little?
These questions:
Don’t stem from lack of data.
But because the data is abundant.
The real challenge is dispersed data
Member data:
In the main database.
Course usage records:
In another system.
Support tickets:
Stored separately.
Marketing performance:
Maintained elsewhere.
Team definitions:
Documented manually.
So before every weekly operational meeting, someone usually:
Exports data.
Confirms date ranges.
Updates spreadsheets.
Prepares dashboards.
Identifies data changes.
Then asks:
Where should we focus?
Assuming this takes 3 hours every Monday
Of those 3 hours, the truly valuable judgment time is likely less than expected.
Most time is spent on:
Locating data.
Confirming fields.
Comparing to last week.
Segmenting members.
Updating charts.
Repeated number checks.
Only then does analysis begin.
The Data agent is best suited to take over this initial part.
First principle: Don’t ask AI to “analyze the whole company”
Initially, the team doesn’t request:
“Help me find what problems the company has recently.”
Instead, they establish a fixed:
Weekly Retention Review.
The AI only answers:
Are there any anomalies in member renewals this week worth addressing?
The scope is narrowed first.
Second step: Fix official metrics
The team defines:
Retention.
Active Members.
New Subscribers.
Churn.
All per the company’s official definitions.
The Data agent does not just pick any column that looks like a renewal rate.
Because if KPI definitions changed weekly,
even the nicest dashboard won’t be comparable.
Third step: Fix comparison periods
The Data agent fixedly compares:
The most recent complete 7 days,
with the previous full 7 days.
For special cases like:
Big promotions, holidays, or annual events,
they also add year-over-year comparisons.
This way, the Data agent doesn’t guess each week “what to compare,” but runs on consistent rules.
Fourth step: AI first finds the biggest anomaly, not analyze all at once
For example, overall retention might drop slightly this week, looking insignificant.
But the Data agent digs deeper:
New members: normal.
Annual subscribers: normal.
Old monthly subscribers: significant drop.
Digging further:
This drop concentrates on members who barely opened any courses in the last 30 days.
Now the problem becomes tangible and actionable.
The AI’s first task is to “narrow down”
From 1,200 members, originally all had to be examined.
Now it’s reduced to a single:
Segment with noticeable change.
Humans no longer need to review all members anew,
only understand what happened to this group.
Next, reviewing Course Usage
The Data agent finds:
These members have fewer logins recently.
The course completion rate has also fallen.
This is a fact.
But it cannot directly conclude:
“Members cancel because the courses are bad.”
Further investigation is needed.
Checking Support Tickets
Supposing the same member group’s support tickets have not increased,
then there is currently:
no clear evidence that “support quality caused cancellations.”
Next, checking course content updates,
they might find:
This group’s favorite series had no new content in the last three weeks.
This forms a:
testable hypothesis worth exploring.
But AI cannot directly announce a cause
The team mandates that the Data agent weekly categorizes results into:
Confirmed changes.
Possible drivers.
Next validations.
It must not rewrite correlation into cause.
This prevents meetings from going down the wrong path from the start.
Fifth step: Data agent automatically updates the Weekly Dashboard
After confirming metrics and queries, the dashboard remains consistent every week with metrics for:
Retention.
New Subscribers.
Active Members.
Course Usage.
Support Volume.
Segment Changes.
No need to build reports from scratch every week.
The Data agent’s role becomes:
Update + anomaly detection.
Not:
Reinventing analysis weekly.
Sixth step: Only bring anomalies into the operational meeting
Previously:
Preparations took 3 hours before meetings,
then another hour was spent during the meeting finding problems.
With the new process:
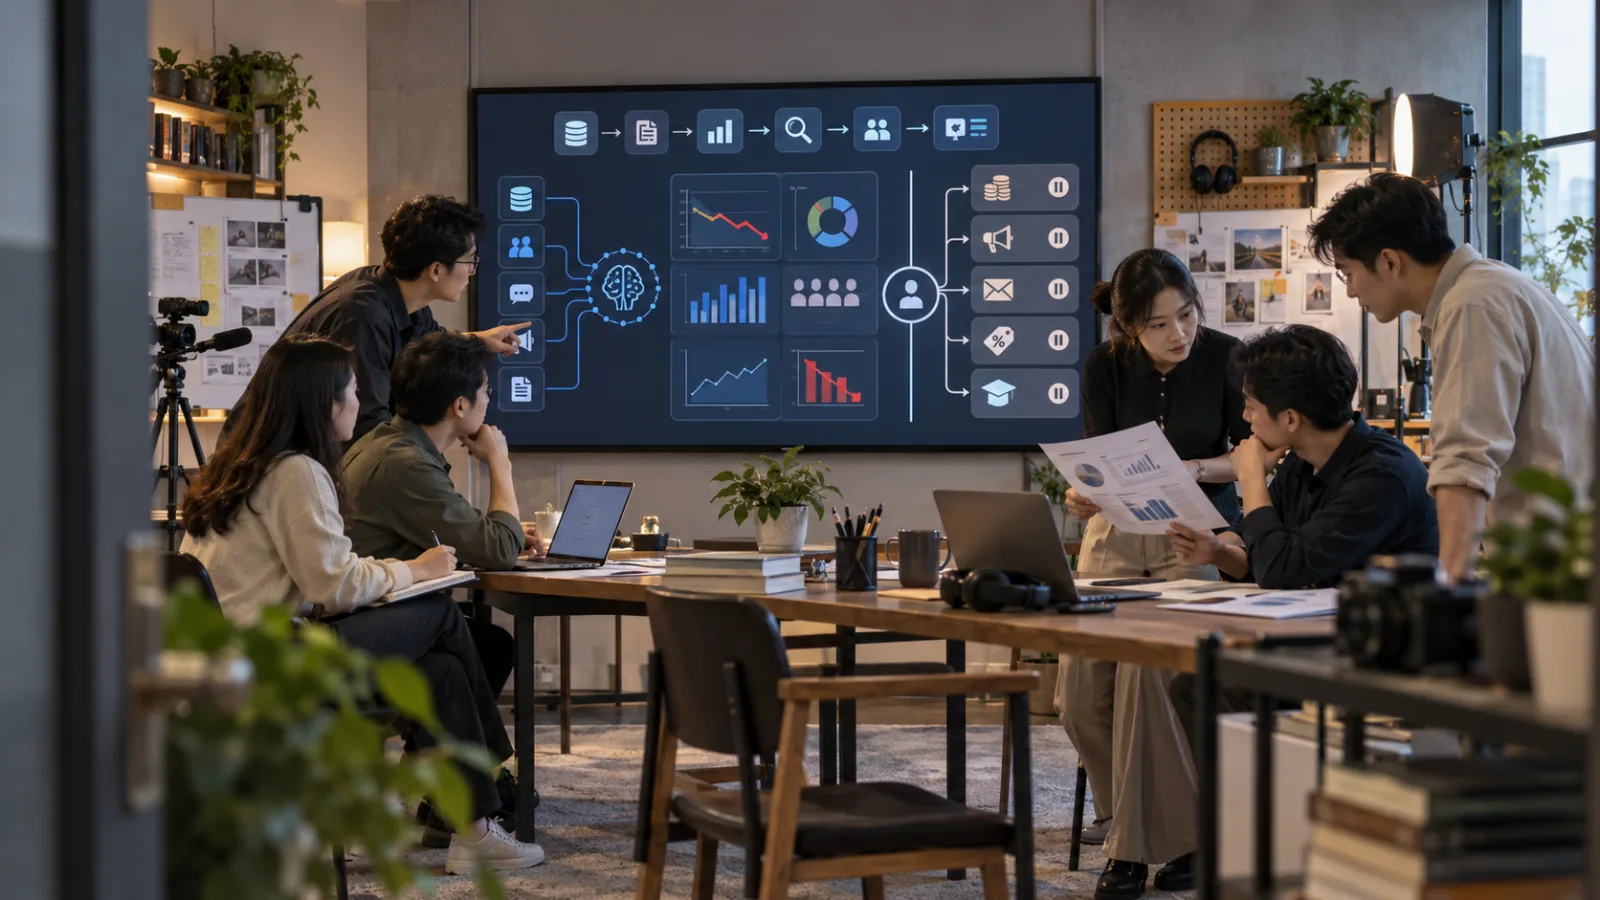
AI completes fixed comparisons, segmentation, dashboard updates, anomaly ranking, and evidence organization before the meeting.
The team starts meetings directly with:
“What are the top three anomalies this week?”
This is where Data agent adds value beyond “automatically drawing charts”
Creating charts is just the final step.
The real time saver is avoiding weekly repetition of:
Data gathering.
Report pulling.
Period comparisons.
Segment slicing.
And figuring out what’s worth focusing on.
AI tackles the front half of investigation.
But several tasks remain human responsibilities
First:
Adjusting prices.
Seeing retention drop, AI cannot automatically apply a 20% discount.
Second:
Stopping ads.
A channel’s lower retention does not mean the ads are worthless.
Customer mix may differ.
Third:
Sending re-engagement emails.
AI can draft the email,
but human review is needed on audience, offer, tone, and commitments in initial tests.
Fourth:
Changing course roadmaps.
Data can tell member usage,
but cannot alone decide what to teach next season.
Why must these remain with humans?
Because they truly change the business.
Wrong analysis can be retraced.
Wrong pricing directly hits customers.
Stopping ads wrongly loses traffic.
Sending wrong re-engagement emails affects brand promises.
Incorrect course direction might waste team months building the wrong product.
Therefore:
Analysis can be automated faster.
Decision automation should be much slower.
Seventh step: Turn “possible causes” into small experiments
Suppose the team’s most reasonable hypothesis is:
“Members without new content recently are more likely to churn.”
They don’t immediately revamp the whole course platform.
Instead, test on a small subgroup,
for example:
Launch a new 7-day content recommendation,
or organize existing courses into shorter learning paths.
Then observe changes in:
Usage.
Renewals.
Support volume.
Whether they improve.
This way, Data agent is not just reporting
The workflow becomes:
Data changes appear.
↓
AI detects anomalies.
↓
AI organizes evidence.
↓
Humans confirm hypotheses.
↓
Run small experiments.
↓
Review results next week.
This is the true:
Data → Decision → Test → Learn cycle.
When mature, AI won’t need to answer all questions weekly
The team can standardize requests to find only:
The top three largest changes weekly.
For example:
Retention.
Acquisition.
Usage.
For each, only list:
The largest segment changes.
Evidence.
And issues requiring human judgment.
This prevents meetings from becoming dashboard walkthroughs.
This company can even set simple priority rules
Small changes:
Just record.
Obvious changes:
Highlight in dashboards.
Large changes:
Require human review.
But do not automatically trigger:
Price changes.
Ad stops.
Email sends.
Real actions remain:
Human decisions.
Data agent’s permissions should not exceed employee access
If an operations manager can only see:
Member operational data,
the Data agent should only access the same scope.
There is no need to grant AI access to payroll,
all financial records,
staff data,
or full sensitive client information for doing analysis.
OpenAI’s Data agent design naturally incorporates:
existing table, row, and column permission controls.
This is important.
If company data is messy, AI won’t clean it automatically
For example, Marketing defines Active Member as:
Login once every 7 days.
Product team defines it as:
Usage within 30 days.
Finance says:
Has payment.
When the Data agent arrives,
it may just expose that everyone has been talking about different numbers.
Before adopting a Data agent,
the most valuable step is not to build more dashboards,
but to fix the top five KPIs clearly.
For this 6-person team, no need to start with a large Data Governance project
They can start from the few numbers needed for weekly retention review:
How is Retention calculated?
How is Active Member defined?
How is New Subscriber defined?
Which periods to compare?
What is the official data source?
Clarify this small scope first.
Then test how much repetitive work AI can save
All these numbers are:
Hypothetical estimates from SasaDaily.
Not official OpenAI ROI.
Assuming previously weekly operational analysis preparation took:
3 hours.
After adopting a fixed Data agent workflow:
AI updates dashboards, segments, and lists anomalies.
People spend only:
60 minutes checking:
Definitions.
Evidence.
Exceptions.
And decide next steps.
This means theoretically saving 2 hours weekly in prep time
Assuming 4 weeks per month,
that’s roughly:
8 hours.
If an operations manager’s effective hourly rate is:
NT$700,
8 × 700 =
Approximately:
NT$5,600 per month.
But this is not:
“Using Data agent guarantees saving NT$5,600.”
Because it doesn’t include:
Tool fees.
Data integration.
Initial setup.
Data cleaning.
Manual verification.
And true success rate.
This is just an estimate of whether a small pilot is worthwhile.
More important KPIs are not just hours saved
First KPI:
Preparation time.
Used to be 180 minutes.
Now?
Second:
After finding anomalies, how long does it take humans to judge?
Third:
How often do analysis results require redo?
Fourth:
How many weekly findings turn into effective experiments?
Fifth:
Does AI’s wrong definition lead the team the wrong way?
These are much more important than:
“Generating dashboards in seconds.”
OpenAI’s early enterprise cases follow similar principles
ServiceTitan:
Uses Data agent not just to build charts,
but analyzes customers who use AI Sidekick Atlas versus those who don’t,
and improves onboarding accordingly.
Turing:
Monitors operational metrics,
investigates underlying drivers,
and improves onboarding and customer satisfaction.
The real value is not:
“AI making reports.”
But:
“Reports turning faster into the next question.”
This 6-person education team ends with a simple weekly process
Monday:
Data agent updates fixed dashboards,
finds biggest anomalies,
lists evidence.
The team checks:
Sources,
Metrics,
Periods,
Filters.
Then discusses only real exceptions.
Selects a minimal experiment.
The next week:
Review results.
Thus, AI takes over:
The repetitive analysis process,
not the
company management responsibility.
This is the ideal entry point for a Data agent
If a company has someone every week:
Pulling the same numbers,
Doing the same comparisons,
Segmenting the same way,
Then spending half a day finding problems,
This is a very worthwhile AI workflow to audit first,
Because it has high frequency, relatively fixed rules,
easy-to-check results,
and mistakes don’t immediately translate into external commitments.
Conversely, don’t start day one with “AI automated management”
Don’t:
Analyze retention,
then automatically:
Change prices,
Stop ads,
Send emails,
Offer discounts.
This turns:
Data errors into
Business errors directly.
Good automation is not:
Removing humans completely,
but:
Freeing humans from weekly repetitive tasks.
For this company, the best first step for AI is not “decide how to save renewal rates”
But rather:
Help find real anomalies worth focusing on each week.
This step is:
Repetitive, time-consuming,
verifiable,
and doesn’t require AI to make promises on behalf of the company.
If this step becomes stable,
then decide what to hand off next.
This is the most practical way to implement AI workflows.
If you want to find which part of your work suits AI best, leave a comment “workflow,” and I can help you figure out where to start.
Today, let’s progress a bit with AI.
Learn one AI technique daily.
Save a little time daily.
Improve a little every day.
SasaDaily, growing together with you.